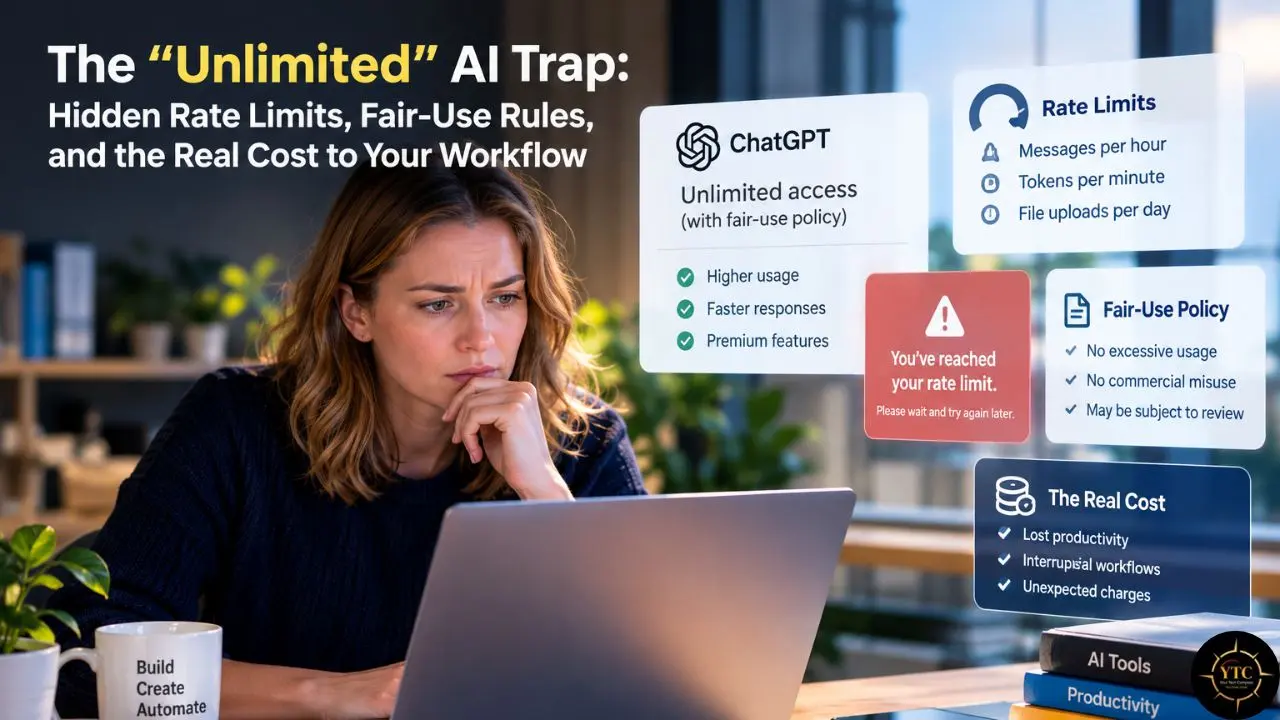
You are two hours from a client deadline, deep in a long conversation with the AI you pay for every month, when a banner appears saying you have reached your limit. The plan’s marketing page said unlimited. Your invoice says you paid for the top tier. Yet the tool has stopped, the reset is hours away, and the work is not finished.
That gap between the word on the pricing page and the meter behind the scenes is what this guide is about. I will walk you through what “unlimited” actually means in AI plans, how ChatGPT, Claude, Gemini, and GitHub Copilot meter usage as of October 2026, and where fair-use rules can create unexpected constraints. Then I will show you what these limits cost your workflow in real terms, and how to avoid the trap, or at least plan around it. I wrote this from official help pages and third-party trackers, not from my own stress-testing of each plan, so I flag every figure that moves quickly.
Quick Answer: No major AI plan makes all of its capabilities unlimited. Most plans meter at least some usage: sessions, weekly activity, compute, credits, premium models, or individual features. Before you pay, find out which meter applies to your work, because the cheapest plan on paper often costs the most in lost time.
What “Unlimited” Really Means in AI Marketing
“Unlimited” is a marketing adjective, not an engineering promise. Running large models costs real compute every time you send a prompt, so providers rarely give you unlimited access to every capability for a flat fee without protecting themselves somewhere. That protection simply hides somewhere different on each plan.
The Six Hidden Meters
Once you know the meters, you can spot them on any pricing page. Here is how they look in practice:
Meter | What It Counts | Where You Meet It | Who Feels It Most |
|---|---|---|---|
Rolling Session Window | Usage inside a short window, such as five hours | Claude, Gemini | Anyone working in long bursts |
Weekly Cap | Total use across a week | Claude, Gemini | Heavy daily users and coders |
Compute or Credit Budget | Tokens, model size, prompt complexity | Gemini, GitHub Copilot, Claude usage credits | Agent and long-context users |
Feature Allowance | Uploads, deep research, images, voice, reasoning effort | Researchers and creators | |
Concurrency or Queue Limit | How many jobs run at once, and how fast | Common in AI video, image, and batch-processing tools | Anyone batching work |
Fair-Use or Reasonable-Use Rule | Whatever the provider calls abuse | Nearly every plan | Automation, shared accounts |
In my view, the fair-use rule is the most important row, because it is the catch-all that sits above every other meter. Even when a plan has no visible counter, that rule lets the provider slow or restrict you.
Rate Limits, Usage Caps and Fair-Use Rules in Plain English
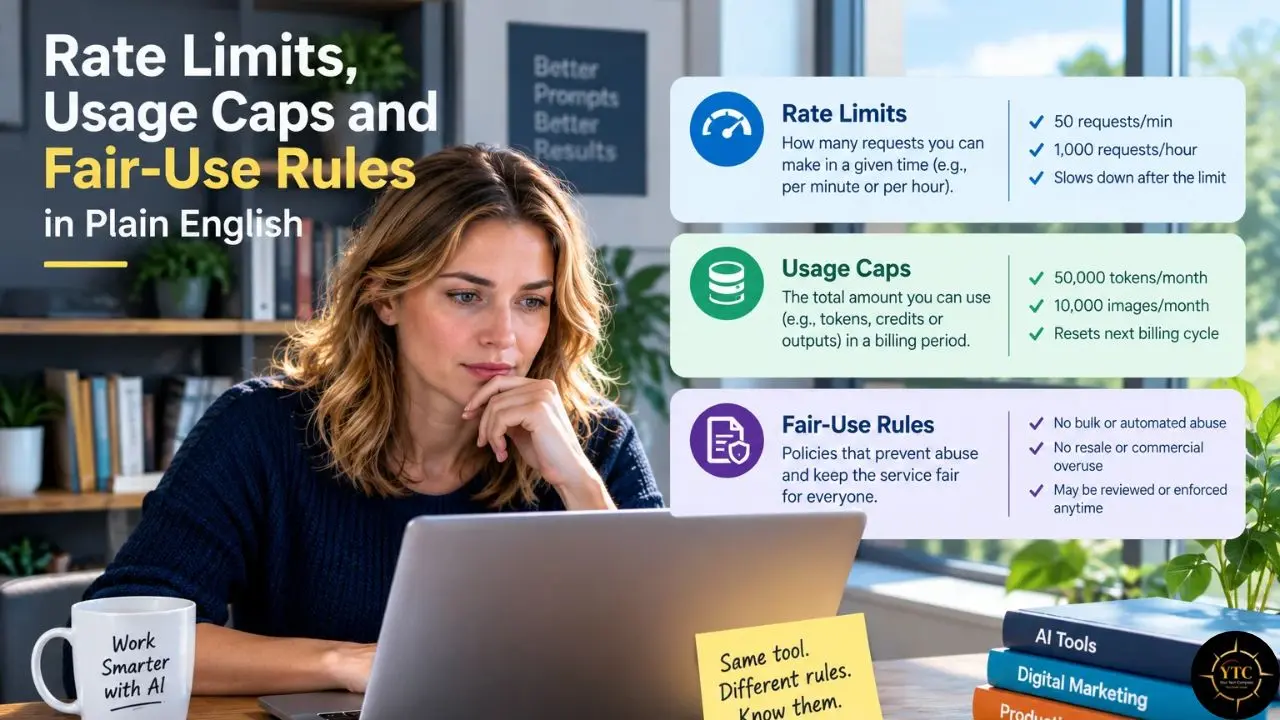
People use these three terms interchangeably, but they describe different things. A rate limit controls how quickly you can send requests or run jobs, often within a minute or an hour. A usage cap controls how much you can consume inside a longer window, such as a five-hour session or a week.
A fair-use or reasonable-use rule is the contractual layer on top. It lets a provider throttle or restrict accounts it considers abusive, even if you never saw a counter. The takeaway: a plan with no visible usage cap can still carry fair-use or reasonable-use rules, so “no message limit” and “no limit” are not the same sentence.
How the Big Platforms Meter You in 2026
Platforms changed their limits repeatedly this year, so a table is the clearest way to compare them. Check the official pages linked below before relying on any number, because these figures can change within weeks.
Platform | What Is Unlimited | What Is Metered | How Limits Reset |
|---|---|---|---|
ChatGPT | Everyday text chat, rolled out across plans following OpenAI’s 6 August 2026 announcement, subject to abuse-prevention safeguards | Reasoning effort, top Pro models, uploads, images, voice, Deep Research, Codex | Per-feature windows; OpenAI no longer publishes a simple fixed message count for everyday chat |
Claude | Nothing outright | Five-hour session limit plus a weekly limit; Max adds a separate weekly limit for Fable; shared with Claude Code | Session every five hours; weekly at a fixed time per account |
Gemini | Nothing outright | Compute-based limits shaped by prompt complexity, model, features, and chat length | Every five hours until a weekly limit |
GitHub Copilot | Code completions | Chat, agent mode, the CLI, and other AI-powered features draw AI Credits (1 credit = $0.01) | Monthly credit allowance |
Grok | Nothing advertised as unlimited | A shared weekly pool since June 2026; pool sizes unpublished | Weekly (official xAI documentation) |
ChatGPT: The Limits Moved, They Did Not Disappear
OpenAI announced unlimited everyday text chat on 6 August 2026, with the change rolling out across its plans; Free and Go users were scheduled to receive it the following week. Trackers read that as the end of message counting. Until then, Plus users faced roughly 160 messages every three hours, plus a separate weekly cap on Thinking mode, according to one tracker. Now the meters sit on reasoning effort, uploads, images, voice, Deep Research, and the highest-tier Pro models.
Here is the catch: OpenAI’s help documentation, as reported, does not document unlimited use of its highest-tier Pro model. Pro tiers now reportedly sit at $100, $200, and $500, so “unlimited” on the headline plan still has a ceiling on the feature you may actually be paying for. If you want the model background, our ChatGPT 5.4 explainer covers what the paid tiers unlock.
Claude: Two Clocks Running at Once
Anthropic’s support page for Claude Code says both Pro and Max plans carry a five-hour session limit and a weekly limit, and Max also has a separate weekly limit for Fable. Those limits are shared across Claude and Claude Code, so a long coding session drains the same pool you use for writing and research. When you run out, you can wait for the reset or enable usage credits to keep going.
Anthropic states Max multiples against Pro’s per-session allowance (5x and 20x) but does not publish a weekly multiple. One independent tracker measured Max 20x at roughly 10x Pro across a full week, though I would treat that as an estimate worth verifying. Our Claude Opus 4.7 explainer explains why heavier models burn allowances faster.
Gemini: Compute, Not Counting
Google’s Gemini Apps help page describes compute-based limits that factor in prompt complexity, the models and features you use, and chat length. Your limit refreshes every five hours until you reach a weekly limit. Google publishes multipliers instead of counts: AI Plus gets 2x standard limits, AI Pro 4x, and AI Ultra 5x or 20x of Pro, depending on the tier.
Depending on the feature and plan, subscribers who hit a limit may be able to continue on a lighter model, which softens the wall but can downgrade quality at the worst moment. In practice, this means a single heavy request, like a long document with extended thinking, can cost far more allowance than twenty quick questions.
Our Gemini 3.1 Pro review shows where that heavier model earns its cost, and our Grok vs ChatGPT comparison covers the other major rival.
GitHub Copilot: Credits Replaced Requests
Since 1 June 2026, GitHub has billed Copilot through AI Credits worth $0.01 each, replacing its older premium-request system. Code completions stay unlimited, but chat, agent mode, the CLI, and other AI-powered features draw from your credit pool based on tokens consumed. Because agent workflows use far more tokens than single prompts, that shift matters most to developers running long sessions.
The Fine Print That Bites: Fair-Use Clauses and Throttling
Start with the wording. OpenAI’s unlimited text chat comes with an abuse-prevention caveat, and Plus usage remains subject to plan limits, abuse guardrails, and temporary restrictions during high demand. Anthropic says usage depends on conversation length, complexity, model, features, and reasoning effort. Google says its limits factor in prompt complexity and chat length.
These phrases share one message: your effective limit is not a fixed number. It flexes with demand, with the model you pick, and with how you work.
That flexibility is why heavy and automated use gets the most scrutiny. Fair-use language can put scripted workloads, parallel agents, and accounts shared between several people under greater scrutiny. If you run a small team off one login, I would treat that as exactly the kind of pattern these rules are designed to catch.
Plans also change underneath you. ChatGPT replaced its old Plus message window with model-specific allowances, Gemini dropped daily prompt counts in May 2026, and Copilot rewrote its billing in June 2026. If your workflow depends on a specific allowance, you inherit the same risk we describe in our piece on AI model churn and retraining costs: the ground moves faster than your process.
The Real Cost to Your Workflow
Price tags understate the problem, because the expensive part of a limit is the interruption. The numbers below are illustrative examples, not measurements, so replace them with your own hourly rate and usage.
Scenario | Illustrative Math | Takeaway |
|---|---|---|
Freelancer locked out near a deadline | 6 lost hours a month × $30/hour = $180, against an $80 monthly step-up from a $20 plan to a $100 plan | Upgrading can be cheaper than waiting |
Developer’s agent loop on a metered API (50 steps, 5M input and 100K output tokens at $0.435 / $0.87 per million) | About $2.26 uncached; about $0.50 with 90% of input read from cache, excluding the initial cache-write cost (assuming cache hits bill at 10% of the fresh-input rate) | Prompt structure and caching can change API cost more than plan choice |
Team of three sharing one seat | One allowance split three ways, plus fair-use risk | Seats are cheaper than lockouts |
Long chat with many files | Every turn re-reads a growing context | Fresh chats stretch limits further |
When Your Agent Eats the Pool
Agentic coding makes the problem sharper. A coding agent loops through tools, reads files, and re-reads its own context, so a single session can use more allowance than a day of ordinary chat. On Claude, that session shares a pool with your regular conversations, and on Copilot, agent sessions spend AI Credits through repeated chat turns, file reads, and tool calls.
If you are evaluating coding agents, our Factory AI review shows how one agentic platform handles this. My read: for agent work, a metered API or a credit-based plan is often more honest than a flat subscription that quietly rations you.
When Tools Quietly Inflate Your Context
Connecting more tools usually means more instructions and definitions in every request. If you are wiring assistants into your stack, our guide to the Model Context Protocol explains how those connections work, and why each one adds weight to the context your plan has to process. A leaner setup often stretches an allowance further than a bigger plan does.
Hidden Limits in Creative and Video Tools
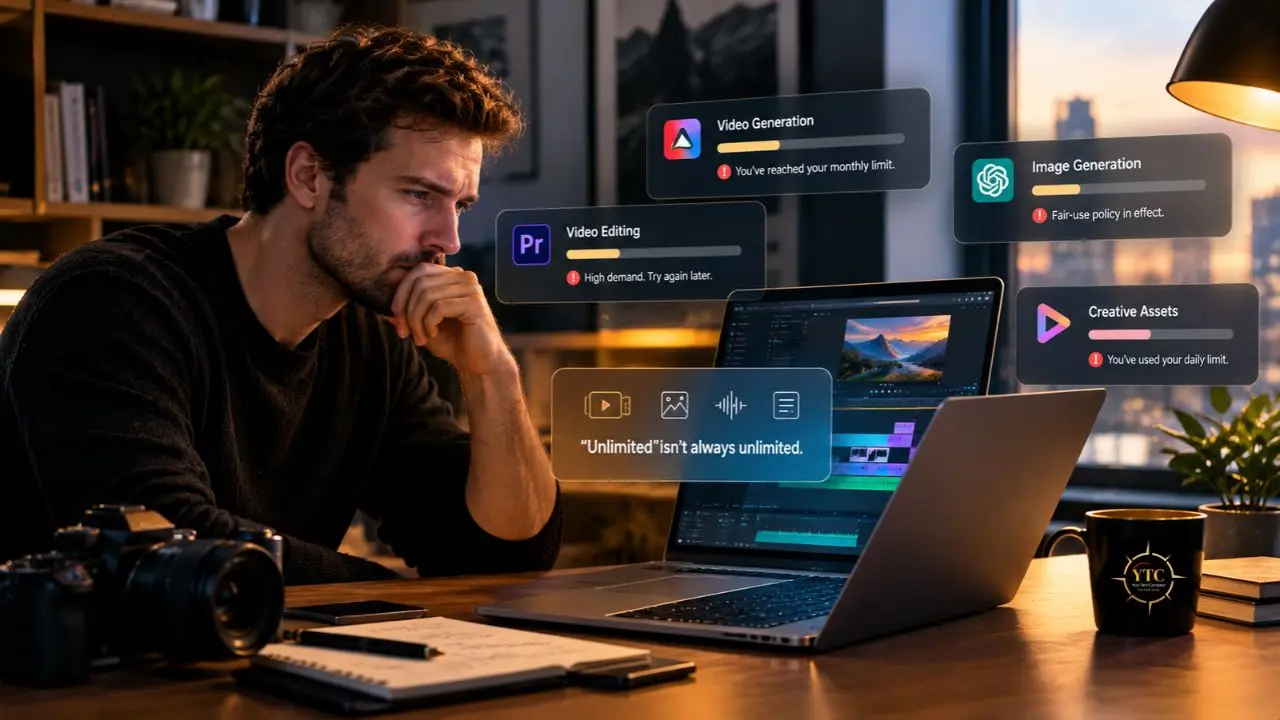
Image and video tools hide their limits differently. A third-party review of advertised “unlimited” AI video plans in August 2026 found that “unlimited” can still mean unlimited generation at a standard queue speed, with concurrency caps, model exclusions, and fair-use throttling attached. Envato is a different kind of limit: it moved AI generation to credits on 17 August 2026, with monthly allowances that vary by plan and video generation consuming more credits than many other AI actions.
Three questions expose most of the trap. Is the unlimited period time-limited? How many jobs can run at once? And do model, resolution, duration, or output-quality restrictions shrink the plan below what you need? A plan that is unlimited but slow can still miss your deadline.
How to Spot the Trap Before You Pay
Before you subscribe, put these questions to the pricing page and the help center:
- Is there a weekly cap in addition to a session window?
- Is one allowance shared between chat, coding tools, and agents?
- Do premium or reasoning models have their own separate limit?
- Does the fair-use clause mention automation, shared accounts, or peak hours?
- What happens at the limit: a hard stop, a downgrade to a lighter model, or paid overage?
- Is the reset time published, or do you find out by hitting the wall?
Watch the wording as well. Phrases like “highest limits,” “near-unlimited,” “priority access,” and “fair use applies” each signal a meter the page may not be showing. If you cannot find the allowance in writing, treat the plan as capped.
Practical Ways to Stretch Your Limits
You can often stretch your effective allowance without paying more. The key is matching the model and the context to the task.
- Route by difficulty. Send simple drafting to lighter models and keep heavy reasoning for tasks that need it. Frameworks like LangChain make this kind of routing practical for teams.
- Start fresh chats. Long threads carry their full history into each new request, so a new conversation with a short summary uses less context. Prompt caching can reduce the cost of reprocessing an unchanged history, but it does not remove the underlying context limit.
- Retrieve instead of pasting. Pulling only the relevant passages into a prompt is usually cheaper than uploading whole documents, and retrieval with vector databases is one proven way to cut inference cost.
- Plan around resets. Check your reset time in settings and schedule heavy work right after a window refreshes.
- Cap your spending. Where credits or overage exist, set a spending limit before a long session, not after the bill.
When the API or Open Models Make More Sense
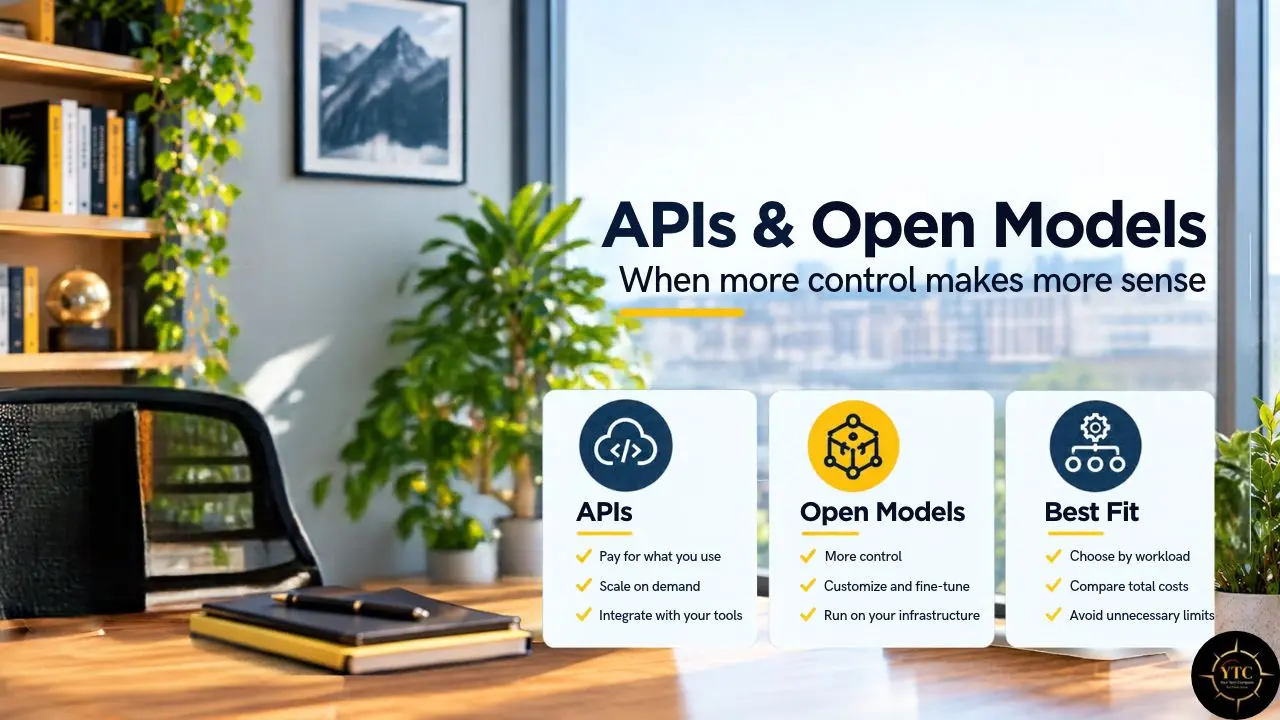
Sometimes the honest answer is to leave the flat-rate plan. The API charges per token, publishes rate limits, and makes the pricing model transparent, so you pay for exactly what you use. For high-volume or automated work, that visibility often beats a subscription that rations you silently.
You also have open-weight options. A hosted platform such as Together AI serves open models by the token, and if you want full control, our guide to running open-source LLMs locally and safely shows the realistic route. For alternatives to compare, see our reviews of Qwen 3, GLM-4.7, and Llama 4, and browse more in AI Unboxed.
What This Means for African Users and Teams
Pricing is the first hurdle. Many providers bill in dollars, so a $100 or $200 tier can equal a large share of monthly income in many African markets, and a lockout that forces an upgrade hurts more. That is why I would test the free or entry tier thoroughly before stepping up.
For teams, sharing one account is tempting but risky, since fair-use clauses can prohibit shared logins. Team or business seats may cost less than the lost hours from a throttled shared account. Long chats and large uploads also use bandwidth as well as allowance, which matters on mobile data.
Policymakers and regulators can help too. In my opinion, consumer-protection rules should push providers to publish plain-language limits and reset times, because opaque meters hit price-sensitive users hardest. Explore related coverage in our African Tech and AI in Africa sections.
FAQs
No plan I found is unlimited in every respect. ChatGPT makes everyday text chat unlimited, but it still meters reasoning, uploads, images, voice, and premium models. Claude, Gemini, and Copilot meter most advanced features through session windows, compute, credits, or premium-request allowances.
A rate limit controls how fast you can send requests, usually per minute. A usage cap controls how much you can consume across a window such as five hours or a week. You can hit one without hitting the other.
It lets the provider slow, restrict, or suspend accounts it considers abusive, even when no visible counter exists. Automation, shared accounts, and heavy agent use can be targets. Read the terms before you build a workflow on a flat plan.
Both providers use rolling five-hour allowances inside a weekly ceiling, which spreads demand and stops one burst from consuming a whole week. For you, the practical effect is that hitting a limit is often temporary. The weekly ceiling is the one that stops you for longer.
It depends on your volume and how well you structure prompts. At low-cost API rates, a heavy agent loop can cost a few dollars or even cents with good caching, while light users may find a $20 plan cheaper. Run your own numbers using real token counts.
Match models to tasks, start fresh chats, retrieve instead of pasting, and check your reset time before heavy work. Set spending limits where credits exist. For critical deadlines, keep a backup tool or an API key ready.
True North in a Metered World: Your Tech Compass on AI Limits
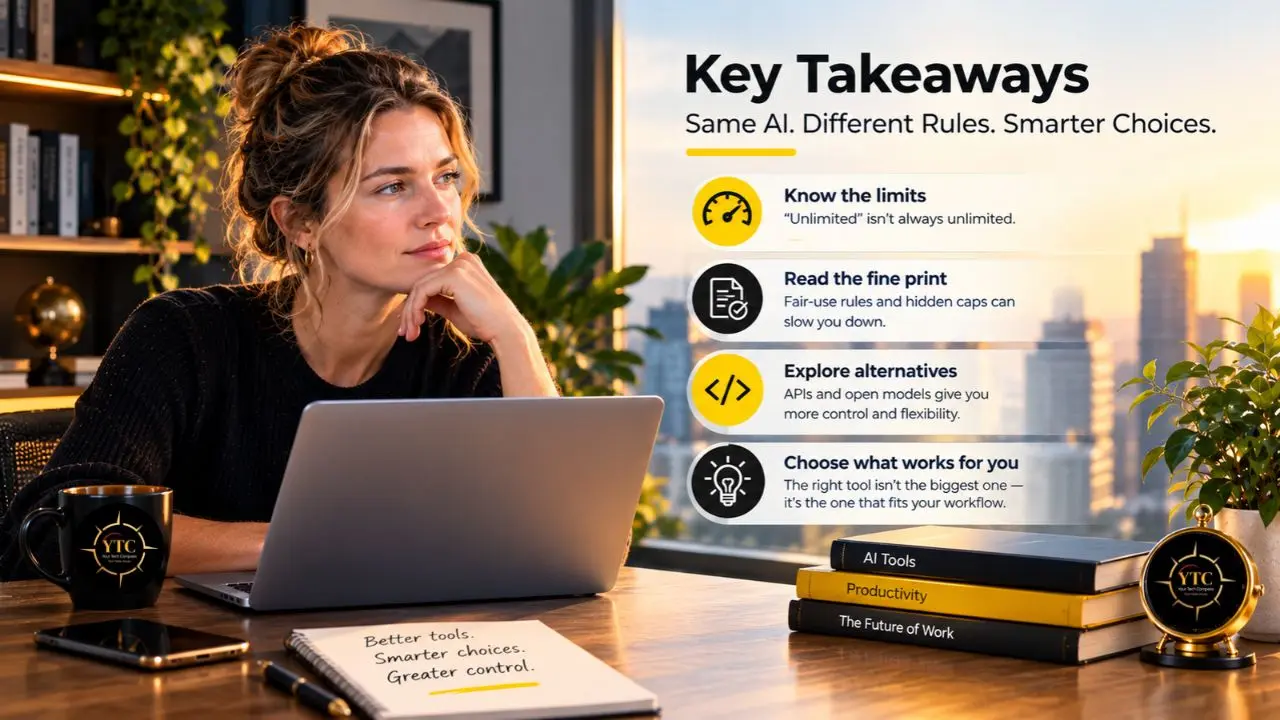
The lesson of this year is that “unlimited” has become a moving target. ChatGPT freed up text chat but moved its meters onto features, Gemini replaced prompt counts with compute, and Copilot swapped requests for credits. Every change looked generous from one angle and tighter from another, which is why I would judge any plan by its meters, not its headline.
If you are an individual or a freelancer, price your lost hours before you pick a tier, and keep a fallback tool for deadlines. Developers should treat flat plans as convenience and metered APIs as infrastructure, with spending limits switched on from day one. Policymakers and business leaders across Africa, meanwhile, should push for plain-language limit disclosures so that price-sensitive users can budget with confidence.
Before you pay for the next “unlimited” plan, read the fine print with us at YourTechCompass.com.